Go to MPAI-PAF V1.6 AI Modules
Function
Ref. Model
I/O Data
SubAIMs
JSON MData
Profiles
Ref. Software
Conformance
Performance
1 Functions
The Videoconference Client Transmitter (PAF‑VCT) AIM is used in the Avatar-Based Videoconference Use Case.
The functions of the Videoconference Client Transmitter are to:
- Receive from a Participant:
- Input Audio from the microphone.
- Input Visual from the camera.
- Participant’s Avatar Model.
- Participant’s Language Selector (e.g., EN-US, IT-CH).
- Send to the Server:
- Speech Object (for Authentication).
- Face Object (for Authentication).
- Input Portable Avatars containing:
- Language Selector (at the start).
- Avatar Model (at the start).
- Input Speech.
- Avatar Descriptors.
2 Reference Model
Figure 1 depicts the Reference Model of the Videoconference Client Transmitter (PAF‑VCT) AIM.
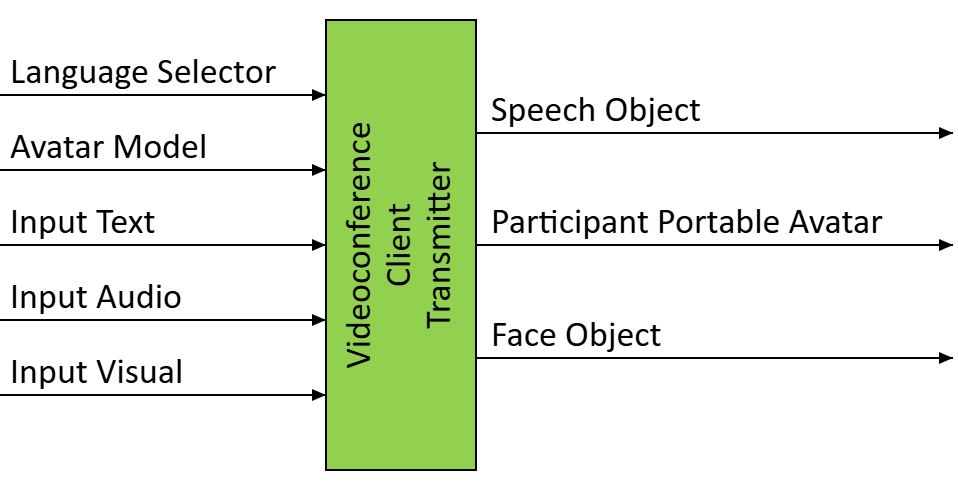
Figure 1 – Reference Model of the Videoconference Client Transmitter (PAF‑VCT) AIM
3 I/O Data
Table 1 gives the Input and Output Data of the Videoconference Client Transmitter (PAF‑VCT) AIM.
| Input | Description |
| Input Text | Chat text used by a participant to communicate with Virtual Meeting Secretary or other participants |
| input Selector | The language(s) a participant wishes to speak and hear. |
| Input Audio | Audio of a participants’ Speech in a meeting room. |
| Input Visual | Visual of participants in a meeting room. |
| Avatar Model | The avatar model selected by the participant. |
| Output | Description |
| Speech Object | A participant’s utterance used by Server for authentication. |
| Participant Portable Avatar | Portable Avatar produced by Client Transmitter. |
| Face Object | Participant’s face used by Server for authentication. |
4 SubAIMs
4.1 Reference Model
Figure 2 depicts the Reference Model of the Videoconference Client Transmitter (PAF‑VCT) Composite AIM. Red text refers to Data sent at the start of the meeting.
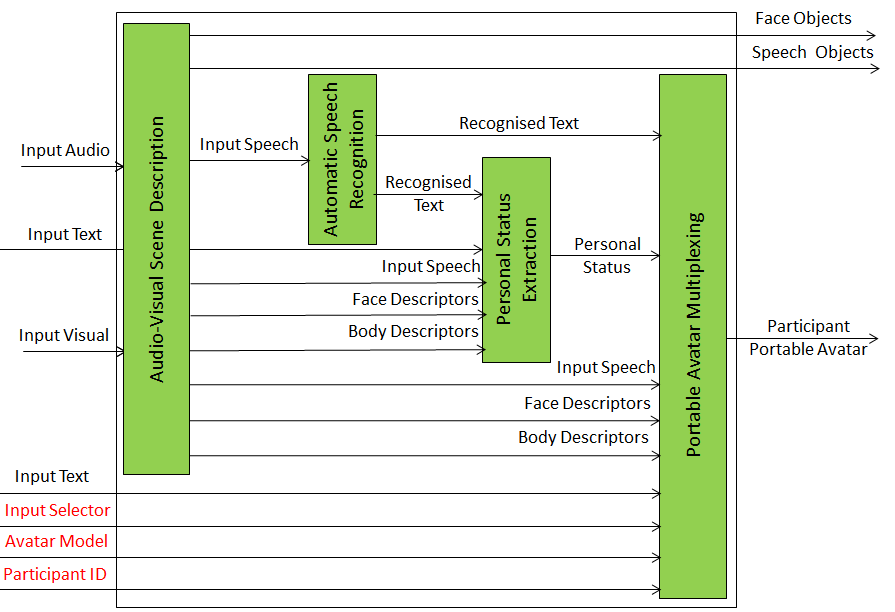
Figure 2 – Reference Model of the Videoconference Client Transmitter (PAF‑VCT) Composite AIM
4.2 Operation
At the start, each participant provides:
- Language Selector
- Avatar Model.
- Speech Object (for Authentication).
- Face Object (for Authentication).
- Participant ID
During the videoconference:
- Audio-Visual Scene Description produces Speech Objects, Face Objects, Face Descriptors, Body Descriptors and Audio-Visual Scene Geometry.
- Automatic Speech Recognition produces Recognised Text.
- Personal Status Extraction produces Personal Status.
- Portable Avatar Multiplexing multiplexes Recognised Text, Personal Status, Input Speech, Face Descriptors, Body Descriptors, Language Selector, Avatar Model, and Participant ID.
- Videoconference Client Transmitter sends Portable Avatars to Avatar Videoconference Server that the Server processes and re-distributes to Client Receivers.
4.3 Functions of SubAIMs
Table 2 gives the functions of the Videoconference Client Transmitter (PAF‑VCT) SubAIMs.
| SubAIM | Function |
| Audio-Visual Scene Description | 1. Receives Input Audio and Input Visual. 2. Provides Input Speech, Speech Object, Face Descriptors, Body Descriptors, Face Object. |
| Automatic Speech Recognition | 1. Receives Input Speech. 2. Provides Recognised Text. |
| Personal Status Extraction | 1. Receives Recognised Text, Speech, Face Descriptors, Body Descriptors. 2. Provides the Participant’s Personal Status. |
| Portable Avatar Multiplexing | 1. Receives Language Selector, Avatar Model, Input Text, Input Speech, Recognised Text, Personal Status, Participant ID, Face Descriptors, Body Descriptors. 2. Provides Participant Portable Avatars. |
4.4 I/O Data of SubAIMs
Table 3 gives the Input and Output Data of the Videoconference Client Transmitter (PAF‑VCT) SubAIMs.
| SubAIM | Input | Output |
| Audio-Visual Scene Description | Input Audio Input Visual |
Input Speech Speech Object Face Object Face Descriptors Object Body Descriptors Object |
| Automatic Speech Recognition | Input Speech | Recognised Text |
| Personal Status Extraction | Recognised Text Input Speech Face Descriptors Object Body Descriptors |
Personal Status |
| Portable Avatar Multiplexing | Recognised Text Personal Status Input Speech Face Descriptors Object Body Descriptors Object Input Text Language Selector Avatar Model Participant ID |
Portable Avatar. |
4.5 AIMs and JSON Metadata
Table 4 provides the links to the AIM specifications and JSON schemas. AIM1 indicates the Composite AIM and the other columns its SubAIMs.
| AIM1 | AIM2 | AIM3 | AIM4 | Name | JSON |
| PAF-VCT | Videoconference Client Transmitter | X | |||
| OSD-MSD | Audio-Visual Scene Description | X | |||
| OSD-ASD | Audio Scene Description | X | |||
| CAE-AAT | Audio Analysis Transform | X | |||
| CAE-ASL | Audio Source Localisation | X | |||
| CAE-ASE | Audio Separation and Enhancement | X | |||
| CAE-AST | Audio Synthesis Transform | X | |||
| CAE-AMX | Audio Descriptors Multiplexing | X | |||
| OSD-VSD | Visual Scene Description | X | |||
| OSD-AVA | Audio-Visual Alignment | X | |||
| MMC-ASR | Automatic Speech Recognition | X | |||
| MMC-PSE | Personal Status Extraction | X | |||
| MMC-ETD | Entity Text Description | X | |||
| MMC-ESD | Entity Speech Description | X | |||
| PAF-EFD | Entity Face Description | X | |||
| PAF-EBD | Entity Body Description | X | |||
| MMC-PTI | PS-Text Interpretation | X | |||
| MMC-PSI | PS-Speech Interpretation | X | |||
| PAF-PFI | PS-Face Interpretation | X | |||
| PAF-PGI | PS-Gesture Interpretation | X | |||
| MMC-PMX | Personal Status Multiplexing | X | |||
| PAF-PMX | Portable Avatar Multiplexing | X |
5 JSON Metadata
https://schemas.mpai.community/PAF/V1.5/AIWs/VideoconferenceClientTransmitter.json
6 Profiles
No Profiles.
7 Reference Software
Not part of this specification.
8 Conformance Testing
Table 5 provides the Conformance Testing Method for the Videoconference Client Transmitter (PAF‑VCT) AIM. Conformance Testing of the individual SubAIMs is given by the individual AIM specifications.
If a schema contains references to other schemas, conformance of data for the primary schema implies that any data referencing a secondary schema shall also validate against the relevant schema, if present, and conform with the Qualifier, if present.
| Receives | Input Text | Shall validate against Text Object Schema. Text Data shall conform with Text Qualifier. |
| input Selector | Shall validate against Selector Schema. | |
| Input Audio | Shall validate against Audio Object Schema. Speech Data shall conform with Audio Qualifier. |
|
| Input Visual | Shall validate against Visual Object Schema. Visual Data shall conform with Visual Qualifier. |
|
| Avatar Model | Shall validate against 3D Model Object Schema. Speech Data shall conform with 3D Model Qualifier. |
|
| Produces | Speech Object | Shall validate against Speech Object Schema. Speech Data shall conform with Speech Qualifier. |
| Participant Portable Avatar | Shall validate against Portable Avatar Schema. Portable Avatar Data shall conform with respective Qualifiers. |
|
| Face Object | Shall validate against Visual Object Schema. Face Data shall conform with Visual Qualifier. |
9 Performance Assessment
Not part of this specification.
