Function
Ref. Model
I/O Data
SubAIMs
JSON MData
Profiles
Ref. Software
Conformance
Performance
1 Functions
The Multimodal Input Harmonisation (PGM‑MIH) AI Module assembles the audio, visual, textual, and paralinguistic evidence available about a scene into a single Harmonised Multimodal Context, in which each item of evidence is placed on a common time base and attributed to the User that produced it, by
- Establishing a common time base across the modality streams.
- Attributing the Text Descriptors and the Speech Descriptors to the User that uttered them, using the Audio‑Visual Scene Descriptors to carry the attribution across modalities.
- Reconciling the Entity identifiers used by the several modalities into one harmonised set.
- Recording the gaps, the disagreements, and the unattributed evidence found while doing so.
- Producing the Harmonised Multimodal Context.
The module is assembling and reconciling. It should not interpret the evidence it harmonises: it establishes what was observed, when, and by whom, and leaves interpretation of the evidence to the analysis AI Modules of User State Description, which consume its output. This AIM may require a degree of intelligence obtained through contextual training.
Multimodal Input Harmonisation does not repeat the audio‑visual association performed by the Audio‑Visual Alignment (PGM‑AVA) AIM. Rather, it receives the Audio‑Visual Scene Descriptors from the ASE and VSE AIMs and adds textual correspondence.
2 Reference Model
Figure 1 depicts the Reference Model of the Multimodal Input Harmonisation (PGM‑MIH) AIM.
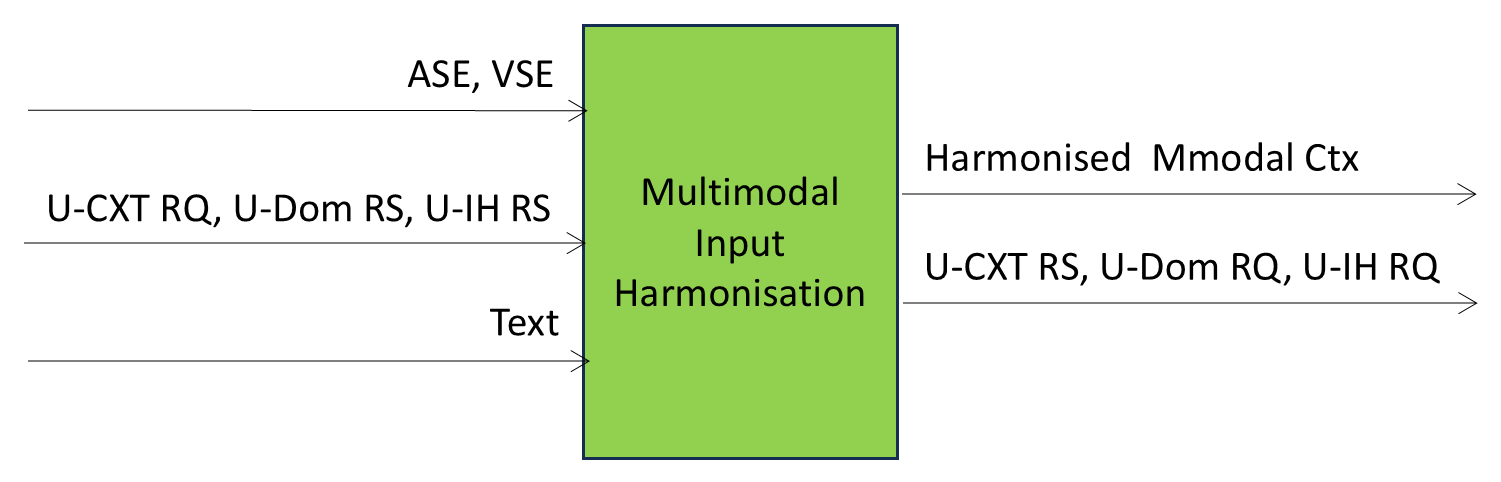
Figure 1 – The Multimodal Input Harmonisation (PGM‑MIH) AIM
The Multimodal Input Harmonisation (PGM‑MIH) AI Module operates as follows:
- Receives the Enhanced Audio Scene Descriptors, the Enhanced Visual Scene Descriptors, the Text, and the Speech Descriptors.
- Establishes a common time base by:
- Referring the segment boundaries of each stream to the corresponding capture times.
- Resolving the differing rates at which the streams are produced.
- Marking the intervals for which a stream is absent.
- Establishes referential correspondence by:
- Attributing each Text segment and each Speech Descriptor to the User that produced the utterance.
- Carrying that attribution to the corresponding Visual Entity through the Audio‑Visual Scene Descriptors.
- Binding the harmonised media to the User, identified by the User CXT Request.
- Reconciles the media identifiers used by the modality streams into one harmonised set, retaining the original identifier of each modality.
- Records:
- Evidence that could not be attributed to any media.
- Disagreements between modalities about certain media.
- Streams that are absent, incomplete, or outside the tolerance of the common time base.
- Constructs a consistent Harmonised Multimodal Context.
- Outputs the Harmonised Multimodal Context for use by downstream AI Modules.
The module operates in real time, without exploiting the reasoning capability of Basic Knowledge and without Model Context Protocol interactions. The AIM queries Domain Access and, through the Controller, the Interaction History kept in Private Storage to obtain the necessary information.
3 I/O Data
Table 1 specifies the Input and Output Data of the Multimodal Input Harmonisation (PGM‑MIH) AIM.
| Input | Description |
|---|---|
| Enhanced Audio Scene Descriptors | Audio Scene Descriptors augmented by Audio Scene Enhancement with derived and semantic properties. |
| Enhanced Visual Scene Descriptors | Visual Scene Descriptors augmented by Visual Scene Enhancement with derived and semantic properties. |
| Audio‑Visual Scene Descriptors | Correspondence and spatial relations between the Audio Entities and the Visual Entities of the scene, produced by Audio‑Visual Alignment. |
| Text Descriptors | Text Descriptors of the text recognised by Automatic Speech Recognition from the speech component of the scene. |
| Text Object | The text of the User: the text recognised by Automatic Speech Recognition and the text typed by the User. |
| Speech Descriptors | Paralinguistic features of the speech segment produced by Automatic Speech Recognition. |
| User CXT Request | The control directive specifying scope, tolerance, and policy constraints for harmonisation, and identifying the User where known. |
| User Domain Response | Domain‑specific knowledge supporting the reconciliation of evidence across modalities. |
| User Interaction History Response | Prior interaction‑history content supporting the persistence of harmonised media identifiers across perceptual episodes. |
| Output | Description |
| Harmonised Multimodal Context | Audio, visual, textual, and paralinguistic evidence of the scene, placed on a common time base and attributed to harmonised Entities, with a record of media instances that could not be harmonised. |
| User CXT Response | Response describing the execution and outcome of Multimodal Input Harmonisation processing. |
| User Domain Request | Query to Domain Access for domain‑specific knowledge. |
| User Interaction History Request | Query to Private Storage for prior interaction‑history content. |
4 SubAIMs
No SubAIMs.
5 JSON Metadata
https://schemas.mpai.community/PGM1/V1.0/AIMs/MultimodalInputHarmonisation.json
6 Profiles
No Profiles.
7 Reference Software
Not part of this specification.
8 Conformance Testing
Table 2 provides the Conformance Testing Method for the Multimodal Input Harmonisation (PGM‑MIH) AIM.
If a schema contains references to other schemas, conformance of data for the primary schema implies that any data referencing a secondary schema shall also validate against the relevant schema, if present, and conform with the Qualifier, if present.
| Receives | Enhanced Audio Scene Descriptors | Shall validate against Enhanced Audio Scene Descriptors schema. |
| Enhanced Visual Scene Descriptors | Shall validate against Enhanced Visual Scene Descriptors schema. | |
| Audio‑Visual Scene Descriptors | Shall validate against Audio‑Visual Scene Descriptors schema. | |
| Text Descriptors | Shall validate against Text Descriptors schema. | |
| Text Object | Shall validate against Basic Text Object schema. | |
| Speech Descriptors | Shall validate against Speech Descriptors schema. | |
| User CXT Request | Shall validate against User CXT Request schema. | |
| User Domain Response | Shall validate against User Domain schema. | |
| User Interaction History Response | Shall validate against Interaction History schema. | |
| Produces | Harmonised Multimodal Context | Shall validate against Harmonised Multimodal Context schema. |
| User CXT Response | Shall validate against User CXT Response schema. | |
| User Domain Request | Shall validate against User Domain schema. | |
| User Interaction History Request | Shall validate against Interaction History schema. |
9 Performance Assessment
Not part of this specification.
